Articles • by Edwin Sanchez • November 03, 2026
Ask three vendors what “sync” means, and you’ll get three answers. Here’s a plain-English one, along with how it differs from integration and from lookalikes like replication and migration. Where syncs come apart gets its own section, and so does picking a tool.
What does data synchronization do? It keeps a record identical in every system that stores a copy. Update a customer’s phone number in one app and the others follow, so nobody calls the old one.
Now take it away. In a typical company, sales is in the CRM and finance is in the ERP, marketing has an automation tool, support has a helpdesk, and the analysts sit over in the warehouse. One person fixes a phone number in one app and moves on. Soon orders disagree between systems and reports stop matching. Data silos run up that tax, and plenty of teams pay it daily.
The rest of this page is a plain-language tour of data sync. It sorts sync from integration first, then from replication and migration, and it explains one-way and two-way, real-time and batch along the way. You’ll also see how a sync runs step by step and where it breaks, then how to pick a tool. Skyvia’s own synchronization gets an equally close look, limitations included.
What Is Data Synchronization, in Plain Terms?
Change a record in one app, and data synchronization makes sure the rest know what you did. It spots the change in one system and applies it wherever else the data lives, so every system agrees on the latest version. Direction varies (one way or both) and so does timing, live or on a schedule. The goal doesn’t: a single version of each record.
The average number of apps a typical company uses grows every year. CRMs and ERPs are only the start. Add analytics tools and cloud databases – that’s only the base here. What follows depends on your business, workflow, team’s preferences, etc. Okta’s 2025 Businesses at Work report puts the average at more than 100 apps per customer worldwide, a 9% rise on the year before. If there’s nothing to align copies that live across those apps, they drift apart.
Examples are easy to find; here are a few of the most prominent ones:
-
Finance dashboards need current figures because some very important and pricey decisions get made on the balance the dashboard shows.
-
In healthcare, patient records have to match from one system to the next because everyone involved in a person’s care should be reading the same story, whichever system they happen to open.
-
Retailers want the same stock levels in every store because “in stock” on the website is a promise that better not be broken.
-
SaaS platform that mirrors customer data between regions needs each region to tell the same story because replication lag is a recovery point in disguise.
Before we dive deeper, let’s take a moment to sort out the terminology.
Sometimes, “synchronization” is reserved for two-way exchange only. Everything that is one-way is called “replication.” And sometimes the term is used to cover both. We belong to the second category. Whenever direction matters, we say “one-way” or “two-way.”
Why Data Synchronization Pays Off
Data comes from all over, all the time. That stream doesn’t have weekends. But since the sources hardly ever talk to each other, we get silos. Add to that the fact that the average number of tools only gets bigger, and you get more chances for records to slip out of step. Spooky, isn’t it?
Data synchronization “connects” tools that were never built to work together, so people and systems act on the same facts.
What Data Synchronization Gets You
Here’s why data synchronization is more than copying data between systems:
-
Better decisions because the information is finally consistent and current. Example: point-of-sale data flows into a retail chain’s inventory system, so managers spot what’s selling and move stock or promotions between stores.
-
Faster workflows, since nobody has to retype anything. Example: a SaaS company hooks its CRM up to its billing platform. Close a deal in the CRM and billing raises the invoice.
-
A better customer experience, since every team sees the whole picture. Example: a support agent opens a ticket on a delayed order and sees logistics’ shipping status next to finance’s payment status, all in one place.
-
Cleaner reporting and compliance, since the records are accurate and complete. Example: a healthcare provider syncs patient data between clinics and its central records system. Audits and reports take less time, which helps with HIPAA requirements.
-
Easier scaling, because a new system joins an existing flow rather than forcing a rebuild. Example: a fintech company opens in a new region and plugs local banking APIs into the platform it already runs.
Data Synchronization Compared with Integration, Replication, Migration, and Backup
Sync, integration, replication, migration, and backup might sound alike. You can’t put an equals sign between these, though.
Data integration pulls data from several sources into one place (e.g., a dashboard or a warehouse). The original systems don’t necessarily change. Say a CRM sends sales data to an analytics platform every day. That’s integration. Now say a customer’s email changes in the CRM and the support tool updates to match. That one is synchronization.
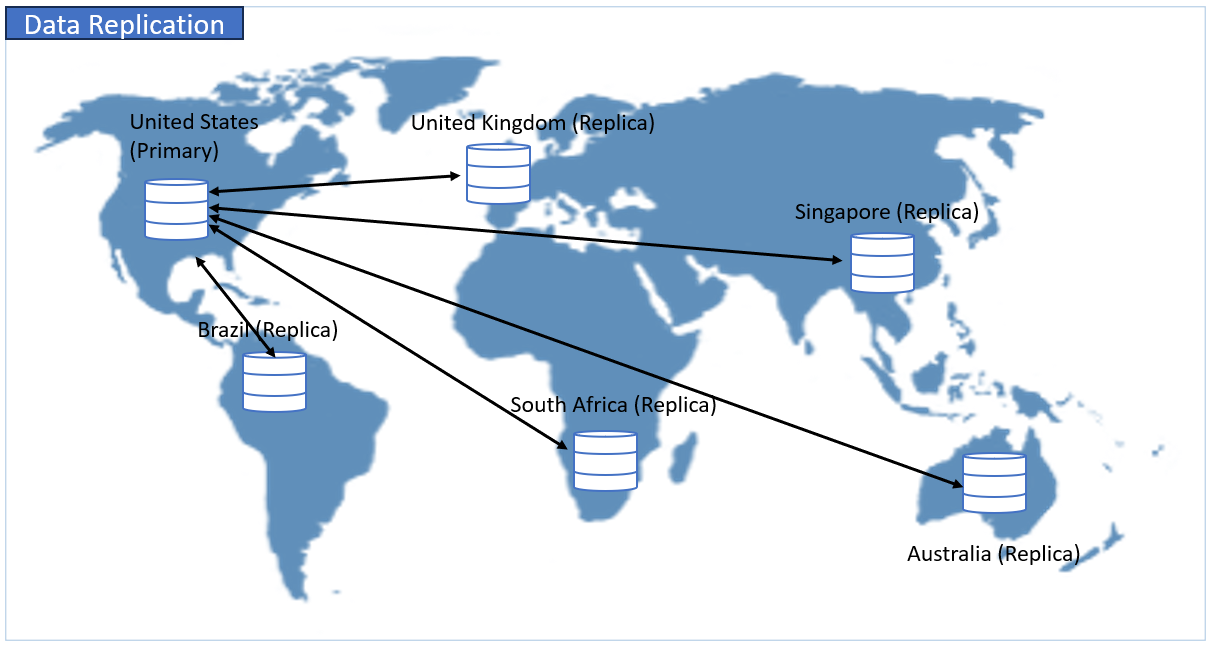
Data replication copies data from one place to another, usually as is. Its main task is to create backup data for disaster recovery and faster reads. One example is a production database replicated to a read-only reporting server, so analysts can run heavy queries without dragging down the live system. Replication can run one way or between several nodes, as in the diagram below. What sets data synchronization apart is that it tracks what changed on each side and decides what to do when both sides changed. Our guide to data replication covers the topic in depth.
Data migration is normally a one-off move from one system to another, often during an upgrade or a platform change. Once it ends, there are no more updates. Our guide to data migration goes into the details. Sync, by contrast, is ongoing. Say a company moves its old HR data to a new cloud system. That is migration. Keep the HR and payroll systems aligned afterward, so employee details stay current in both, and that’s synchronization.
Backup means a point-in-time copy for recovery. It does not keep two live systems aligned.
| Concept | What it does | Direction | Timing | Example |
|---|---|---|---|---|
| Data synchronization | Keeps records consistent between systems | One-way or two-way | Continuous or scheduled | A CRM update appears in the helpdesk |
| Integration | Combines data from several sources in one place | Usually one-way | Batch or real-time | CRM, ads and website data in one dashboard |
| Replication | Copies data to another store, usually as is | One-way or between several nodes | Continuous or scheduled | Read-only copy of a production database |
| Migration | Moves data permanently to a new system | One-way | One-time | Moving to a new HR platform |
| Backup | Keeps a copy for recovery | One-way | Scheduled | Nightly snapshot of a database |
Six Data Synchronization Use Cases You’ll Meet Often
Every department’s system knows something another department’s system needs to hear. The cases below each name the two systems and the trigger that starts the sync, then show the damage when it’s missing.
Syncing a CRM with Marketing Tools
Sales and marketing are tightly connected, but they usually keep their eggs in different baskets. What happens with no sync between them? Some contacts never get reached, while others get the same email twice.
Example: a sales rep at a software company gets a new lead in Salesforce as soon as it’s submitted through a HubSpot form, and can follow up right away. Marketing sees what comes next.
Syncing Online Store Inventory with ERP
Customers can only order what a store says is in stock, so wrong inventory sends them after things that aren’t there. The outcome is canceled orders and bad reviews.
Example: Shopify handles a retailer’s sales and NetSuite its supply. When a customer buys, NetSuite updates the quantity, and Shopify shows the new stock level, which puts an end to overselling.
Moving SaaS App Data to Cloud Warehouses
Plenty of companies entrust their data to cloud apps. Reporting means pulling data out of every one of them.
Example: a subscription service sends Stripe charges and Zendesk tickets into BigQuery. The data team can then see whether billing problems and slow support are feeding churn.
Keeping HR and Payroll Systems in Step
People get hired, promoted, and leave – the circle of life in every company. When HR and payroll don’t get updated together, paychecks and tax details come out wrong.
Example: an HR manager enters a raise in BambooHR, and by the next payday the change has reached ADP. Nobody enters it twice.
Linking Point-of-Sale Systems to Accounting Software
When the point-of-sale system isn’t linked to accounting software, somebody ends up exporting files and fixing errors by hand.
Example: a bakery rings up sales on Square and keeps its books in QuickBooks. Each night the day’s sales, tips, and taxes sync over, so the owner has clean records at tax time.
Feeding AI Agents and Analytics
An AI agent with outdated data is still an AI agent. It’s just one that’s very good at being confidently wrong.
The stakes depend on the task. Last night’s warehouse refresh might tell analysts everything they need about weekly sales. But if an agent is about to recommend buying another 500 units, yesterday’s inventory count deserves a second opinion.
Example: A retailer loads Shopify sales into BigQuery, where analysts compare them with synchronized NetSuite inventory records. Before suggesting a reorder, an AI agent checks the current NetSuite stock level. Same business data, different demands on freshness.
Main Types of Data Synchronization
Two things set data synchronization setups apart: where the data flows and when it moves. This section covers direction. The next one covers timing.
One-Way Synchronization
One-way sync moves data from a source to a destination, and nothing travels back. That suits destinations with no need to talk back, such as a reporting tool, for instance.
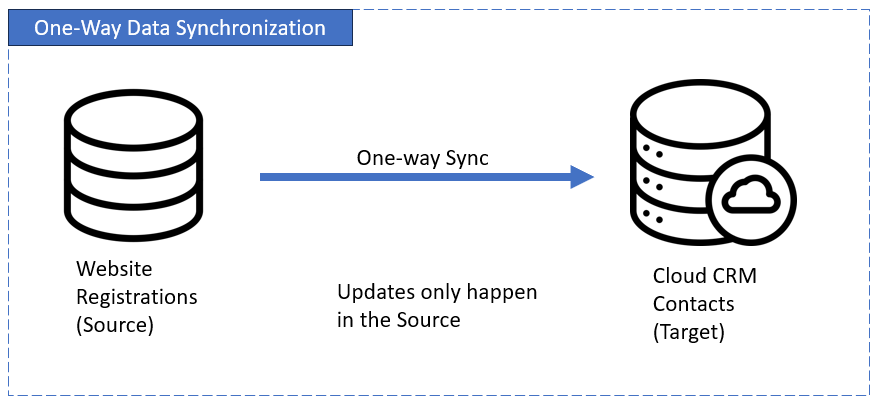
Example: an online store ships daily order data to a business dashboard. The dashboard never pushes anything back.
Two-Way Synchronization
In two-way sync, both systems accept changes. A change in system A reaches system B, and the reverse holds too. It’s a good fit for tools that share the same data, a CRM and a support app, for example. Both sides can edit the same record, so two-way sync needs a rule for conflicts (more on that below).
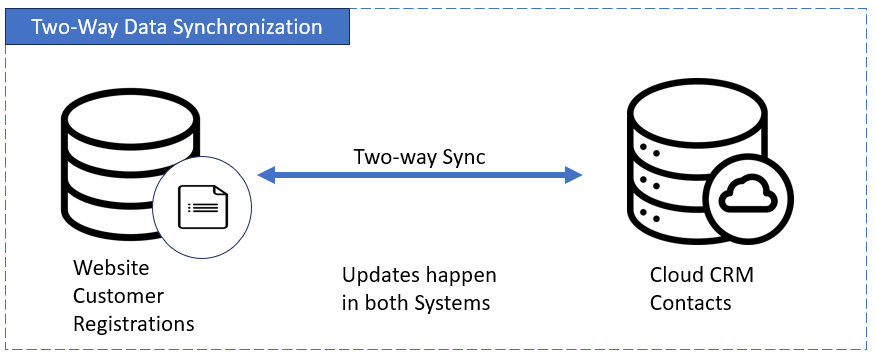
Example: a customer’s email is updated in Salesforce, and the same change appears in Zendesk.
Multi-Way Synchronization
Multi-way sync keeps more than two systems aligned, wherever a change happens. It suits companies with many apps across teams.
Example: marketing updates a lead in HubSpot, and everyone who also needs that data, sees it in their apps: sales in Salesforce, finance in NetSuite, etc.
Hybrid Synchronization
Hybrid sync mixes patterns. Some data goes both ways; other data goes one way or stays read-only. It works when only certain fields should be editable across systems.
Example: either app can edit contacts, but order history flows one way, from the ERP to the CRM.
Real-Time, Near-Real-Time and Batch Data Synchronization
The second way to classify data synchronization is timing, which depends on how a tool finds out that something changed. There are two broad ways. Pull-based sync works like a check-in: the destination, or the sync tool, asks the source for changes, usually on a schedule. Push-based sync flips that. The source sends a change the moment it happens, through a webhook or an API trigger.
Event-based sync is a push set off by a particular event, like a sale or a sign-up.
Poll on a schedule and you get batch or near-real-time sync. Pushing events gives you something close to real time. A sync that checks for changes every five minutes is near-real-time at best; however, often the marketing page says “live”.
| Timing | How changes are detected | Typical use | Example |
|---|---|---|---|
| Real-time | Webhooks, events or a database change log | Customer-facing tools, fraud checks, live dashboards | A payment update reaches billing as it happens |
| Near-real-time | Frequent polling, from every minute to every few minutes | Operational data that can lag briefly | Contacts in a CRM and a helpdesk |
| Batch | A scheduled job, hourly or nightly | Large volumes where speed matters less | Product reviews sent to analytics at midnight |
Real-time data synchronization has this aura that makes it look better. We can’t deny that it is incredibly useful, but only when all the stars align because it costs more to build and to monitor. Moreover, many workflows, such as nightly reporting, gain nothing from it. Skyvia Synchronization runs on a schedule, so it sits in the near-real-time and batch rows (details in the Skyvia section below).
Detecting Changes: Full, Incremental and CDC
Timing aside, every sync has to decide how much data to move on each run.
| Technique | What it moves | When to use | Example |
|---|---|---|---|
| Full sync | Every row and column, changed or not | Small datasets, first loads, occasional refreshes | A retail analytics tool pulls all product data every night |
| Incremental sync | Only records added or changed since the last run, found through a timestamp column such as LastModifiedDate | Large tables where a full copy would be too heavy | A CRM exports contacts updated in the last 24 hours to a marketing platform |
| Change data capture (CDC) | Row-level inserts, updates, and deletes read from the database’s change log | Near-real-time needs, and cases where deletes must be tracked | A financial system updates account balances and removes closed accounts in a reporting database |
Of the three, CDC is the most granular, because a timestamp column can’t tell you a row was deleted. The catch is that the source database has to offer a change log, and many SaaS apps don’t.
Four Ways to Synchronize Data
Once you know what you need, you can pick from four common ways to synchronize data.
| Approach | How it works | Strength | Weak spot |
|---|---|---|---|
| Custom code | Scripts and jobs that call the APIs of both systems | Full control over logic | Your team owns authentication, rate limits, retries, conflicts, and API changes, indefinitely |
| Native integrations | A connector built into one of the apps | Quick to switch on, often free | Covers only the apps that the vendor chose, with few options |
| RPA | Software that copies data through the user interface | Works when no API exists | Can break when a screen or field moves |
| Integration platform or ELT tool | A no-code or low-code service with prebuilt connectors, mapping and scheduling | Fast setup, monitoring included | The platform’s limits apply: supported objects, schedules, conflict options |
Custom code isn’t off the table. If the logic is unusual, or the volume is high enough to justify the upkeep, writing your own can be the right call. Just price in that upkeep honestly. A script that works on day one still has to get through API changes and expired tokens, as well as rate limits. As for the usual path, it starts with a native integration and, once that’s outgrown, moves to a platform.
Data Synchronization Methods Outside Databases
Where else does sync show up? Here are the main methods:
-
File synchronization is when you save a file once, and it’s current wherever else you use it, on any device or system. Example: a sales rep edits a proposal from their home device and opens the new version on the office laptop the next morning.
-
Version control, Git for one, syncs files as well. It also tracks changes over time, which is how you roll back a change, or branch and merge. Example: when two developers touch the same feature, Git merges both sets of edits.
-
Between databases, it’s all about consistency. One way or both ways, the data stays in step. Example: a patient portal and an internal records system both keep addresses. One changes, the other follows.
-
Distributed file systems spread files over servers or locations but present a single repository, and synchronization keeps the copies consistent. Cloud storage services lean on them behind the scenes. Example: project files live on a company’s servers in two cities, and staff in both open the same shared folder and see the same files.
-
Mirroring holds an exact copy of the data on another system, and when the primary goes down, the mirror takes over. You choose between two modes here: Synchronous mirroring confirms a write on both systems, while asynchronous mirroring can lose the most recent changes. Example: an online store’s primary database server fails, and the mirror takes over. Under synchronous mirroring, the latest orders are there; under asynchronous, the last few might not be.
How Data Synchronization Works, Step by Step
Calling data synchronization “file copying” sells it short. It’s closer to an engineering process, and the clearest way to see that is a typical database sync, here with customer data moving from an e-commerce system to a CRM.
Step 1: Decide What Gets Synced
Do you want all records or will recent changes suffice? Do you need whole records, or will specific fields be enough? It’s important to set these principles before you start since syncing something no one needs will only eat your budget and bandwidth.
Example: To keep the system adaptable, a company’s sync covers just customer names and contact details that changed in the last 24 hours.
Step 2: Find What Changed
Next, the sync has to work out what changed, which usually comes down to a timestamp column or a change-tracking feature. Database syncs commonly match rows by primary key. A key found only in the source becomes an insert, a key whose row differs becomes an update, and, if the tool supports it, a key deleted in the source gets removed in the target.
Example: the customer table has a last_updated column, so each run pulls only the rows newer than the previous run.
Step 3: Clean Up and Prepare the Data
Data often needs reshaping first: splitting fields, converting types, mapping columns from one system to another.
Example: the e-commerce database keeps a name in one field, while the CRM wants first and last names apart. So “John Doe” is split into “John” and “Doe” before it’s sent.
Step 4: Send the Data Across
Its majesty the sync. Data travels through an API, a database connection, or a scheduled job to reach its destination.
Example: every hour, an API call pushes customer updates into the CRM.
Step 5: Handle Conflicts and Errors
If you’re syncing a pair of systems, prepare that one record might change in both, or a run might die halfway. The first issue has no power over your workflow if you have conflict rules. The second one can’t hurt if you use error handling and reruns.
Example: the newer edit wins when the same record changes in both systems. When an update fails, the sync logs it and tries again in the next job.
Step 6: Check That It Worked
Log how many records were updated, skipped, or failed, and alert someone if a run goes wrong.
Example: more than 10 failed records, and you get an update in your team’s Slack channel. There’s no chance something might break and stay like this behind your back.
Common Challenges in Data Synchronization
On paper, everything looks simple, even data synchronization. In practice, things are a bit harder for different reasons. These are the problems that hit teams most often.
Latency and Lag
Data doesn’t always sync right away, so dashboards and systems can show old information exactly when someone needs a current view. And when you don’t know that there was some kind of lag, you risk building something using outdated data.
Example: a retailer updates stock in the warehouse system, yet an item gets a few extra minutes on the website. Just enough time for someone’s impulsive purchase. And just like that, an order turns into a support ticket.
Conflict Resolution
When two systems change the same record in different ways, you need a rule that decides which change wins.
Example: a customer changes their email in the billing portal while support types a different one into the CRM. Which one’s right?
Schema Mismatches
Every system has its own approach to how to structure data. One may store a full name in a single field; another prefers it to be split into two. Sloppy mapping loses data or misreads values.
Example: an HR system sends job titles from a dropdown, but the other app refuses to work with anything else except free text. As a result, some fields don’t map at all or fail to import.
API Limits and Network Hiccups
Go over the API limit, and the vendor blocks or throttles your next requests. And on top of that, network problems can interrupt runs, too.
Example: a marketing platform caps you at 1,000 API calls per hour. The sync job burns through them halfway, and the remaining records wait for the next window.
Data Quality
A sync copies bad data as eagerly as good data. Whatever is wrong in the source will carry over, or even multiply.
Example: a CRM record with no email address syncs to an email marketing tool. It still shows up in reports but can’t be messaged, which skews the campaign metrics.
Security and Compliance Risks
Data that travels through platforms needs encryption and access controls, especially if that data is sensitive.
Example: Health records, which are regulated data, got synced without encryption and broke rules like HIPAA. And now you risk financial fines (that isn’t even the worst-case scenario).
What Happens After a Sync Fails
Sooner or later, a failure will happen (don’t shoot the messenger), so better plan for it earlier.
Whatever happens, what counts is what the tool does next. A good setup logs each failed record with its error, lets the rest of the run finish, shows every run’s status, and tells someone. A poor one stops without letting you know and leaves the two systems half-aligned.
How to Keep a Sync Reliable
We wish data synchronization were “set and forget,” but it isn’t. However, there are some practices that, when promoted to habits, prevent most of the problems we described above.
Pick a Single Source of Truth
One system should always have the upper hand to cut down on conflicts and overwrites. Otherwise, no one knows which version to trust because decisions and records just bounce between platforms.
Example: a CRM gathers customer info from support chat, billing, and email lists. Make the CRM the single source of truth, and updates from other systems get checked against it.
Track Changes with Timestamps or Change-Tracking Fields
A “last modified” column gives the sync something to check, and so does a change-tracking feature. Either way, runs get shorter and API calls fewer.
Example: say a SaaS company keeps a last_modified column in its customer table. Every job reads only rows updated since the last run, which usually makes the run far shorter than a full copy.
Watch Your Runs and Set Alerts
Waiting for a user to flag a problem means you’re already behind. Watch the status of every run instead, and have the team alerted when a job fails or takes far longer than normal.
Example: a clinic runs its patient-record sync every night. If the run fails or overruns, IT gets an alert, so the problem is fixed before any doctor opens an outdated chart in the morning.
Plan for Errors and Retries
A good setup logs each error and keeps going, and it lets you rerun only the part that failed. Temporary failures, such as a rate limit, get retried. Permanent ones, such as a rejected record, go to a person.
Example: orders keep flowing even when an e-commerce sync runs into an API rate limit. The sync waits and retries the requests that failed, and writes them to a log so someone can review them.
Fit the Timing to the Workflow
Two speeds are enough: real-time for the data where delay costs money (e.g., fraud checks or live inventory), and scheduled for everything else.
Example: which data does a bank move immediately? Suspicious transactions, which go to the risk engine as they happen. Monthly reports aren’t in a hurry and run overnight.
Advanced Data Synchronization Concepts
Conflicts, scale, and reliability are three pillars that can make even simple syncs complicated.
Conflict Resolution Strategies
Both systems edit the same record before the next sync runs, and a conflict happens. With no plan, even the cleanest and most structured data gets overwritten, or contradictions travel downstream.
| Strategy | How it works | Fits | Catch |
|---|---|---|---|
| Last write wins | The newest timestamp overwrites the older value | Low-risk fields | Newer is not always more accurate |
| Source wins | One system is the master, and its value wins every collision | Clear ownership and simple audits | The other system’s edits are lost |
| Manual review | The clash is flagged and a data steward decides | Sensitive data and high-value customers | Slower |
| Field-level merge | Non-overlapping changes from both sides are combined into one record | Records edited in different fields by different teams | Needs per-field change tracking and careful testing |
Tools support different strategies, and a conflict rule that’s missing is hard to add when the sync is already running. That’s why we recommend comparing options first.
Tuning Performance for Large Datasets
When millions of rows are poorly tuned, you deal with timeouts and throttling. And if there isn’t enough on your plate, you also need to deal with slow databases. Three changes help most:
-
Start with indexes on the columns you filter by, like
last_modified_dateand primary keys. -
Move records in batches, beginning with a mid-sized batch and measuring.
-
Spread the work over parallel workers by ID range or time window. Don’t forget to cap concurrency so you don’t swamp an API or the target database.
Transactional Integrity and Idempotency in Practice
Two ideas keep pipelines trustworthy when something goes wrong.
-
Transactional integrity: Say a sync writes an order in three steps and the third one fails. Transactional integrity rolls the first two steps back. That is how pipelines avoid half-written records: all or nothing.
-
Idempotency: Now say a network error forces a retry. Idempotency makes sure no duplicates appear. Deduplication tokens make the retry harmless, and so do upserts paired with natural keys.
Data Synchronization Myths
While working on this article, I noticed that the same seven misconceptions about data synchronization keep resurfacing all the time. So, below is our little “MythBusters” section.
Myth #1: “Sync is just backup”
Not quite. Backups preserve recoverable copies from earlier points in time. Sync keeps current data aligned. You better have both, but asking one to do the other’s job is a risky bet.
Myth #2: “Real-time sync means everything is instantly up to date”
Every time you hear or see the word “real-time,” a healthy amount of skepticism will help. Even with CDC, changes still need time to travel from source to destination. Network delays happen. Processing takes time. Sometimes the receiving system simply isn’t ready.
More importantly, “real-time” isn’t a panacea. Not every workflow needs it, and not every workflow can benefit from it. Your monthly finance report probably won’t suffer from a 15-minute delay. An inventory system deciding whether the last item is still available? Different story.
So, instead of “How fast can we sync?” ask “How much delay can we tolerate?”
Myth #3: “Two-way sync is just one-way sync, twice”
This one sounds reasonable, doesn’t it? Now imagine a sales rep updating a customer’s phone number in the CRM. And imagine a support team member changing it in another app. Both updates are valid. Both systems believe they’re right. Now what?
If there are no conflict rules, systems start to fight by overwriting each other. Last-write-wins is one solution, although it can sacrifice a perfectly legitimate update.
Decide which system owns each field before turning on two-way sync. Otherwise, you’re letting two databases settle their differences without a referee.
Myth #4: “A successful sync means the data is correct”
A green checkmark is a win, but, unfortunately, it isn’t a certificate of data quality. What’s more important, sometimes, that checkmark gaslights people into thinking that there’s no need to check the data that arrived in the target. The job succeeded. The business result? Not necessarily.
If you do check, you might find records with missing values. Perhaps a filter excludes something important. Or a deleted record remains in the destination because the change wasn’t captured.
Compare source and destination records, and watch for suspicious changes in the numbers. Your dashboard shouldn’t be the first place you discover something went missing.
Myth #5: “Sync replaces data governance”
Synchronization tools are good at moving data, but deciding whether that data should move is a different job entirely.
Suppose Salesforce says a customer is active, while your billing system says otherwise. A sync can copy either value, but it can’t decide which one represents the business truth without rules.
Someone on your team still needs to define field ownership. Access permissions matter too, as do the rules for valid data. Otherwise, you’re simply distributing confusion more efficiently.
Myth #6: “More frequent syncs mean more accurate data”
Running a sync every minute sounds impressive. But if your mapping is wrong, congratulations: you’re now distributing incorrect data 60 times an hour. Depending on the setup, it can also increase API usage and operating costs.
Start with the freshness your workflow actually needs. Then make sure the data is arriving correctly before turning up the speed.
Myth #7: “Once it’s set up, it runs itself”
This one is every data engineer’s favorite bedtime story. Here’s a more realistic picture:
-
Monday: the sync works just fine.
-
Tuesday: someone changes a field name.
-
Wednesday: you’re explaining why half the dashboard looks suspicious.
Automatic handling can buy you some breathing room, but not permanent immunity. Keep alerts switched on and revisit mappings when needed. Your future self has enough debugging to do already.
How to Choose a Data Synchronization Tool
Before you pick a tool, decide how quickly you need a working sync and how much room you’ll need to grow. These checks matter day to day:
| Criterion | What to check |
|---|---|
| Ease of use | Can a non-developer set it up? Look for visual mapping, guided setup and readable run logs. Custom code gives full flexibility, but you own deployment, retries and on-call. |
| Connectors | Depth matters more than breadth: do the connectors cover your objects, custom fields and filters, and how do they handle API limits? |
| Direction and conflicts | Does it support two-way sync, and which conflict rules can you set? |
| Timing | Which schedule is the fastest on your plan? Does it support events or webhooks if you need them? |
| Scale | Does it use incremental loads or CDC, batching and parallel runs? Can it handle bulk loads? |
| Security and compliance | Encryption in transit and at rest, role-based access, audit trails, and the certifications your industry asks for. For locked-down databases, look for IP allowlisting or an on-premises agent. |
| Errors and monitoring | Run history, per-record error logs, alerts, and a way to rerun only what failed. |
How Skyvia Handles Data Synchronization
Skyvia is a cloud data integration platform with 200+ ready-to-use connectors that don’t require you to write code. Its Synchronization feature keeps two data sources aligned, and each one can be a cloud application or a relational database. Here’s your action plan with Skyvia:
-
You choose which connection is the Source and which is the Target.
-
Map the fields in both directions.
-
Set a schedule.
A database behind a firewall connects through the On-premises Agent.
How a Synchronization Task Runs
On the first run, Skyvia copies data from the Source to the Target and back without checking whether records are already identical, then builds an ID map. That’s why you should start with one side empty.
After that initial sync, runs move only the records changed since the previous run. Skyvia finds them through timestamp fields in cloud applications and through tracking tables and triggers in relational databases. You do not need to add external-ID fields.
What Your Data Needs
| Where the data lives | Requirement |
|---|---|
| Cloud application objects | The object must support INSERT and UPDATE and have a CreatedDate or UpdatedDate field |
| Relational database tables | The table needs an autogenerated primary key |
| Salesforce, Dynamics 365, SugarCRM, Zoho CRM | Use a dedicated Skyvia account for the connection |
Conflicts: The Source Wins
Skyvia’s Synchronization is bidirectional, but the two sides aren’t equal. The Source is always the winner. When the same record is changed in both places between runs, the Source values are applied, and the Target changes are lost.
That holds even when different fields were edited, because Skyvia does not track changes per field. No conflict-rule setting exists, so what matters is which connection you make the Source.
Scheduling
Tasks run on a schedule: every minute on the Professional plan and above, hourly on Standard, and daily on Free and Basic. This is not real-time sync. Skyvia Automation can react to webhooks as they arrive, but that is a separate feature from Synchronization.
Errors and Visibility
Each run gets a status: Succeeded, or Failed with a reason (Integration error, Task errors or Record errors). The Monitor tab shows the five latest runs, the Log tab holds the history, and failed records can be downloaded as a CSV with their errors, so you can fix the data and run the task again. Email alerts for errors are available but off by default, and you set them up per account (see email notifications).
Where Skyvia Synchronization Fits
If you need a scheduled two-way sync between two cloud apps, or a cloud app and a database (all of that without writing code), reach for Skyvia. It’s not your go-to tool for real-time sync or per-field conflict rules. When you need a one-way sync, use Import. For situations when you need to combine several sources in one pipeline, use Data Flow (is available on the Standard plan and above). Log-based change capture is limited to SQL Server.
You can try a first sync on the free plan before you decide.

Data Synchronization Tools
Plenty of data synchronization tools exist, so there is no need to build one from scratch. Each of the following comes at it differently.
Skyvia
Skyvia is no-code, so a non-developer can set up a sync by choosing the Source and Target, mapping fields, and scheduling it. The Synchronization overview explains how it works.
When to use it: to sync a CRM such as HubSpot with a database (our HubSpot to MySQL guide shows how), or to move data between cloud apps such as HubSpot, Google Sheets, and BigQuery on a schedule.
Example: a sales team updates contacts in HubSpot, and an internal MySQL database picks up the changes every hour. For hourly runs, you need the Standard plan or higher.
Qlik Talend Cloud
Talend now goes by Qlik Talend Cloud, sold in four tiers: Starter and Standard, then Premium and Enterprise. Standard is where real-time synchronization with log-based CDC comes in. Hosting can be in the cloud or on client-managed infrastructure, and a hybrid setup mixes the two. It’s more technical than a no-code tool, so it suits teams with complex pipelines and someone to run them.
When to use it: large-scale workflows, custom transformations or hybrid environments.
Example: customer orders sit in a legacy system, and a daily job transforms them and loads them into a modern analytics platform.
HubSpot Data Sync
HubSpot’s data sync runs one way or two ways between HubSpot and other apps. By default, contacts match by email and companies by name or domain. The connections include Salesforce and Microsoft Dynamics 365: for Salesforce, that means contacts and companies, plus deals and activities; for Dynamics 365, cloud-hosted environments. Zendesk is supported too, for contacts and tickets, but ticket sync is one-way.
When to use it: you use HubSpot and want data flowing between it and one of those apps without development work.
Example: a lead changes their details in Salesforce, and HubSpot mirrors the change in its contact record.
Apache NiFi
Apache NiFi is an Apache project built for processing and distributing data. You design flows in a browser-based interface, and NiFi tracks data provenance while applying back pressure whenever a destination slows down. Data engineers who want control and traceability tend to like it.
When to use it: for routing and transforming data, and for moving it in from many sources, such as APIs and databases, or plain files, whether in real time or in batches.
Example: stores send sensor data to a central system. NiFi ingests it from edge devices and enriches it, then hands it to analytics.
Airbyte
Airbyte pulls data from many sources into a warehouse, which makes it closer to one-way replication than two-way sync. It supports full and incremental syncs. On Airbyte Cloud, syncs run at most every 60 minutes on Standard, every 15 minutes on Plus, and every 5 minutes on Pro and Enterprise Flex. Database sources such as Postgres, MySQL, and SQL Server can use CDC.
When to use it: you want an open-source option that loads data into Snowflake, BigQuery, or a similar platform.
Example: you load data from Stripe, Shopify, and Google Ads into Snowflake every 15 minutes, and that interval needs the Plus plan. None of those three sources can use CDC, so the sync is incremental.
Conclusion
The more apps you run for your business, the more you need data synchronization to stay current. If you’re ready to start this path, make four choices to decide how your sync should behave:
-
Direction
-
Timing
-
How changes are detected
-
Who wins a conflict.
Next comes the foundation: plan for failure from day one. It’s not the cheeriest advice, but monitoring and per-record error logs, plus a way to rerun what failed, keep your data protected.
Every tool has limits, and it’s better to hear them up front. A scheduled sync isn’t real-time. A tool that picks a winner for every conflict will lose edits made in the other system.
Want to keep two systems aligned without writing scripts? Create a free Skyvia account and set up your first synchronization task. It’s free, so you can see whether those limits suit your workflows.

FAQ for Data Synchronization
What does data synchronization mean?Data synchronization is keeping the same records consistent across two or more systems. When a record gets changed in one place, the change is also applied to the other systems.
How can you synchronize data?You have four options: custom code that calls both systems’ APIs, native integrations built into one of the apps, RPA that copies data through the user interface, or an integration platform with prebuilt connectors, mapping, and scheduling.
Why use data synchronization?It closes the gaps between systems; every team now works from the same facts. You get fewer duplicates, fewer manual updates, and reports that match.
How does one-way sync differ from two-way sync?One-way sync sends changes from a source to a target. Two-way sync passes changes both ways, so it needs a conflict rule to decide which update wins. Skyvia’s Synchronization is two-way, where the Source always wins. For one direction only, Skyvia uses Import.
How often should I sync my data?Let the workflow set the timing. Go fast or event-driven where delay costs money, and use an hourly or daily schedule for analytics. Skyvia Synchronization runs on a schedule: every minute on the Professional plan and above, hourly on Standard and daily on Free and Basic.
Is data synchronization just a backup?No. A backup is a point-in-time copy you keep for recovery. A sync keeps live systems consistent, which means a bad change can sync into both systems. Many teams run both.
Which software is best for data synchronization?That depends on direction, timing, and volume. Skyvia for scheduled, no-code two-way sync between cloud apps and databases. Qlik Talend Cloud for complex pipelines. HubSpot Data Sync for HubSpot’s native integrations. Apache NiFi for data engineers. Airbyte for one-way warehouse loads.
What goes wrong most often in data synchronization?Conflicts, mostly, along with change drift. Two systems edit one record, or a schema or API limit shifts. With no clear rules or monitoring, duplicates and overwrites creep in.